Kafka on Kubernetes with Strimzi: Node Pools, Storage, and the Parts That Hurt

Quick answer
Strimzi turns a Kafka cluster into a handful of CRDs, and ZooKeeper is gone — brokers and controllers are now KafkaNodePools running KRaft. Installing it is a morning's work. The parts that hurt are storage you cannot shrink, partition rebalancing, and deciding whether you should be running Kafka yourself at all.
- The CRD surface
- A cluster that works
- Controller and broker roles
- Storage: the decision you cannot undo
- Topics and users as Kubernetes objects
12 min read · Kubernetes
Strimzi turns a Kafka cluster into a handful of custom resources, and the ZooKeeper era is over. Current Strimzi runs KRaft only — brokers and controllers are Kafka nodes with different roles, declared through KafkaNodePool objects, with no separate ZooKeeper ensemble to operate. If your mental model of Kafka on Kubernetes includes a three-node ZooKeeper StatefulSet, it is out of date.
Getting a cluster running is genuinely a morning's work. What follows is that path, and then the three things that actually cause pain in production: storage decisions you cannot reverse, partition placement that does not fix itself, and the question of whether you should be running Kafka yourself.
The CRD surface
Everything is under the kafka.strimzi.io API group. Note the version — v1. A great deal of published material still shows v1beta2; check what your operator version serves before copying manifests from a blog post, including this one.
| Kind | Purpose |
|---|---|
Kafka | The cluster: version, listeners, broker config, entity operators |
KafkaNodePool | A group of nodes with roles (controller, broker, or both), replica count and storage |
KafkaTopic | A topic, managed declaratively |
KafkaUser | A user with authentication and ACLs |
KafkaConnect | A Connect cluster |
KafkaConnector | A connector inside a Connect cluster |
KafkaMirrorMaker2 | Cross-cluster replication |
KafkaBridge | HTTP bridge to Kafka |
KafkaRebalance | A Cruise Control rebalance proposal and execution |
StrimziPodSet | Internal — Strimzi's own replacement for StatefulSets |
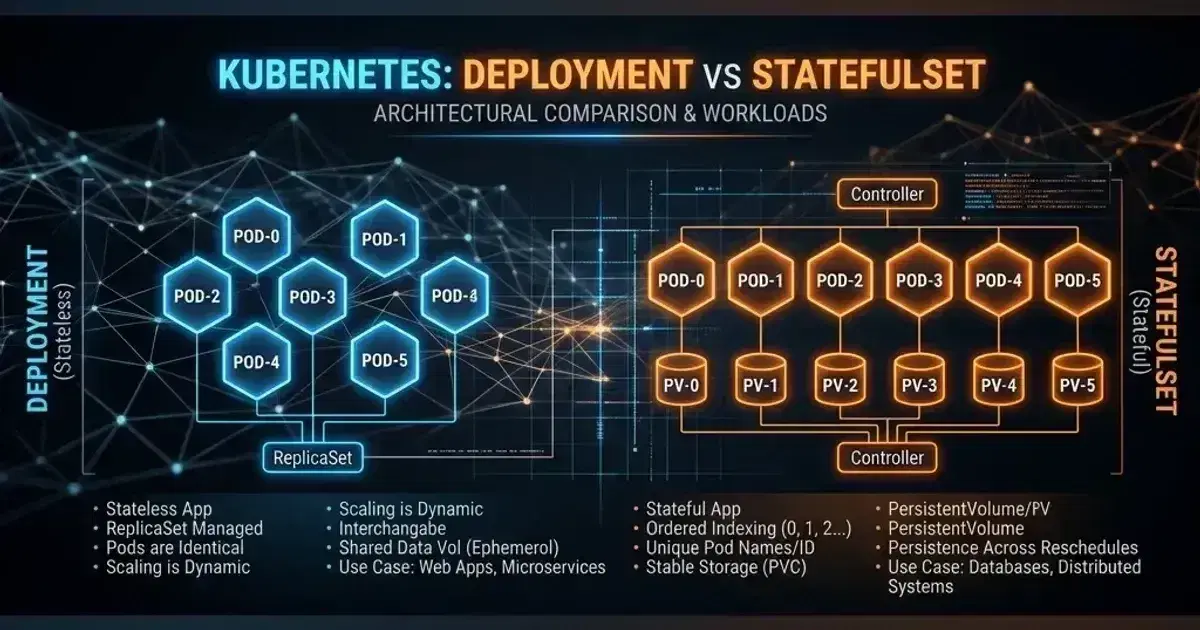
That last one is worth knowing about even though you never write it. Strimzi manages pods through its own StrimziPodSet controller rather than a StatefulSet, because StatefulSet semantics are a poor fit for Kafka — it needs per-pod configuration differences and controlled, non-ordinal rolling. When you go looking for the StatefulSet backing your brokers, there isn't one.
A cluster that works
Three objects: two node pools and the Kafka resource.
1apiVersion: kafka.strimzi.io/v1
2kind: KafkaNodePool
3metadata:
4  name: controller
5  labels:
6    strimzi.io/cluster: my-cluster
7spec:
8  replicas: 3
9  roles:
10    - controller
11  storage:
12    type: jbod
13    volumes:
14      - id: 0
15        type: persistent-claim
16        size: 100Gi
17        kraftMetadata: shared
18---
19apiVersion: kafka.strimzi.io/v1
20kind: KafkaNodePool
21metadata:
22  name: broker
23  labels:
24    strimzi.io/cluster: my-cluster
25spec:
26  replicas: 3
27  roles:
28    - broker
29  storage:
30    type: jbod
31    volumes:
32      - id: 0
33        type: persistent-claim
34        size: 100Gi
35        kraftMetadata: shared
36---
37apiVersion: kafka.strimzi.io/v1
38kind: Kafka
39metadata:
40  name: my-cluster
41spec:
42  kafka:
43    version: 4.3.0
44    metadataVersion: 4.3-IV0
45    listeners:
46      - name: plain
47        port: 9092
48        type: internal
49        tls: false
50      - name: tls
51        port: 9093
52        type: internal
53        tls: true
54    config:
55      offsets.topic.replication.factor: 3
56      transaction.state.log.replication.factor: 3
57      transaction.state.log.min.isr: 2
58      default.replication.factor: 3
59      min.insync.replicas: 2
60  entityOperator:
61    topicOperator: {}
62    userOperator: {}
Several things here are load-bearing.
The strimzi.io/cluster label is how node pools find their cluster. It is a label, not a spec field, and getting it wrong produces node pools that are silently ignored — no error, no nodes.
Replicas and storage live on the node pool, not on Kafka. In older Strimzi you set spec.kafka.replicas and spec.kafka.storage. Those moved. The Kafka resource now describes the cluster's configuration; the node pools describe its shape.
min.insync.replicas: 2 with default.replication.factor: 3 is the durability pairing you want. Three copies, and a write is only acknowledged when at least two are in sync. Drop to min.insync.replicas: 1 and you have a cluster that will silently accept writes it can lose. Set it to 3 and any single broker restart stops writes entirely. Two is the answer for a three-replica cluster, and this is worth getting right before you have data.
entityOperator is what makes KafkaTopic and KafkaUser work. Omit it and those CRs are inert. The empty {} values enable the operators with defaults.
Controller and broker roles
KafkaNodePool takes a roles list. The two shapes:
Separate pools — as above, three controllers and three brokers. Six pods. The controllers handle cluster metadata; the brokers handle data. Failure domains are separated, and you can scale brokers without touching the metadata quorum.
Dual-role — one pool where each node is both:
spec:
  replicas: 3
  roles:
    - controller
    - broker
Three pods total. Cheaper, simpler, and appropriate for development or small production clusters.
The trade-off is real but not dramatic: dual-role nodes mean a broker under heavy data load is also serving metadata, and scaling data capacity means scaling the metadata quorum too. Use dual-role below roughly five brokers and separate pools above it. The migration between them is possible but not free, so if you know you are heading for a large cluster, start separated.
Node pools also let you run heterogeneous brokers — a pool on high-memory nodes for one workload, a pool on cheaper instances for another — by giving pools different template settings and node affinity. That is the underrated capability of the design.
Storage: the decision you cannot undo
This is where teams get hurt, so read this section even if you skim the rest.
1  storage:
2    type: jbod
3    volumes:
4      - id: 0
5        type: persistent-claim
6        size: 100Gi
7        kraftMetadata: shared
Persistent volumes generally cannot be shrunk. You can expand a PVC if your StorageClass sets allowVolumeExpansion: true — and if it does not, you cannot even do that. Going the other way is not a supported operation on any common CSI driver. Provisioning 2 TiB per broker "to be safe" is a bill you pay every month until you rebuild the cluster.
Size from retention, deliberately: peak ingest bytes/sec × retention seconds × replication factor, divided across brokers, plus headroom. Then set allowVolumeExpansion: true on the StorageClass so you can grow into it rather than starting large.
type: jbod is right even with one volume. JBOD ("just a bunch of disks") lets you add volumes later. Starting with type: persistent-claim directly and wanting a second volume later means a migration. The example above is JBOD with a single volume for exactly this reason — it costs nothing and preserves the option.
kraftMetadata: shared tells Kafka to keep KRaft metadata on that volume alongside the data. With multiple volumes you nominate exactly one.
Never use type: ephemeral for anything you care about. It exists for testing and it means exactly what it says: pod restart, data gone.
Use a StorageClass backed by local or fast network SSD, and check the volumeBindingMode. With WaitForFirstConsumer, the volume is provisioned in the zone where the pod schedules — which is what you want. With Immediate, you can end up with a volume in one zone and a pod that cannot schedule into it. See persistent volumes in production for the general version of this trap.
Kubernetes Production Readiness Checklist
The pre-launch checks we run before calling a cluster production-ready — probes, resources, RBAC, upgrades, and backups. Plain Markdown you can commit to your repo.
Free. Instant download. You'll also get the occasional deep-dive from the newsletter — unsubscribe anytime.
Topics and users as Kubernetes objects
With the entity operator running, topics become declarative:
1apiVersion: kafka.strimzi.io/v1
2kind: KafkaTopic
3metadata:
4  name: my-topic
5  labels:
6    strimzi.io/cluster: my-cluster
7spec:
8  partitions: 1
9  replicas: 1
10  config:
11    retention.ms: 7200000
12    segment.bytes: 1073741824
This is genuinely valuable: topic configuration lives in git, gets reviewed, and is applied by a controller. It fits a GitOps workflow directly.
One asymmetry to know: partitions can be increased but never decreased. A KafkaTopic edit that lowers partitions will not shrink the topic. And increasing partitions changes key-to-partition mapping, which breaks ordering guarantees for keyed messages — so it is not a free knob either.
Users work the same way:
1apiVersion: kafka.strimzi.io/v1
2kind: KafkaUser
3metadata:
4  name: my-user
5  labels:
6    strimzi.io/cluster: my-cluster
7spec:
8  authentication:
9    type: tls
10  authorization:
11    type: simple
12    acls:
13      - resource:
14          type: topic
15          name: my-topic
The operator creates the user's certificate and puts it in a Secret named after the user. Mount that into consuming applications. This gets you mutual TLS and per-application ACLs without anyone touching a kafka-acls.sh command.
Rebalancing is not automatic
Kafka does not move partitions on its own. Add three brokers to a cluster and they will sit empty — new partitions land on them, existing ones do not move. Remove a broker without moving its partitions first and you lose replicas.
Strimzi ships Cruise Control for this. Enable it on the Kafka resource, then create a KafkaRebalance:
1apiVersion: kafka.strimzi.io/v1
2kind: KafkaRebalance
3metadata:
4  name: my-rebalance
5  labels:
6    strimzi.io/cluster: my-cluster
7spec:
8  goals:
9    - RackAwareGoal
10    - ReplicaCapacityGoal
11    - DiskCapacityGoal
The workflow is two-phase and this is a good design: the resource first reaches a ProposalReady state where its status shows what would move and how much data that involves. You then approve it with an annotation. Rebalancing terabytes of partition data across a cluster is not something that should happen because someone applied a manifest.
Scaling brokers is therefore a two-step operation, not one. Change replicas on the node pool, then rebalance. Teams that scale up and wonder why load is uneven have done the first half.
Also enable rack awareness so replicas spread across availability zones. Without it, Kafka's replica placement is zone-blind and you can end up with all three replicas of a partition in one zone — which converts a zone outage into data unavailability.
Should you run Kafka on Kubernetes at all?
An honest section, because "yes, here's how" is not always the right answer.
Arguments for self-managing with Strimzi:
- Cost at scale. Managed Kafka is expensive, and the gap widens with throughput.
- No egress charges between your brokers and your apps in the same cluster — often the single biggest line item with an external managed service.
- Full configuration control, including broker settings managed services do not expose.
- No vendor lock-in, and the same setup works in any cluster anywhere.
Arguments against:
- Kafka is a stateful distributed system with genuinely deep operational failure modes. Under-replicated partitions, unclean leader election, log compaction stalls, consumer group rebalance storms. Someone on your team needs to actually understand these.
- Upgrades are a real project. Kafka version, metadata version, and client compatibility all interact.
- Storage operations are slow and risky, as above.
- The 3 a.m. failure is yours.
The honest heuristic: if you have a platform team that already operates stateful workloads on Kubernetes and Kafka is core to your product, Strimzi is excellent and the economics are strongly in its favour. If Kafka is a supporting component and nobody owns it, use MSK or Confluent Cloud and spend the attention elsewhere. The failure mode of self-managed Kafka is not "it costs more" — it is an incident nobody in the room knows how to resolve.
This is the same calculus as databases in Kubernetes, and the answer tends to land the same way.
Frequently Asked Questions
Do I still need ZooKeeper?
No. Current Strimzi is KRaft-only — metadata is managed by Kafka nodes with the controller role, declared in a KafkaNodePool. There is no ZooKeeper ensemble to deploy, monitor, or upgrade. Documentation and tutorials showing a zookeeper section under spec predate this and will not apply cleanly.
What is the difference between separate and dual-role node pools?
Dual-role nodes act as both controller and broker, which means fewer pods and lower cost — appropriate for development and small clusters. Separate pools isolate metadata from data, let you scale brokers without changing the metadata quorum, and are the right shape above roughly five brokers. Migrating between them later is possible but disruptive, so choose with your expected size in mind.
Can I shrink a Kafka broker's storage later?
No. PVC expansion is supported when the StorageClass sets allowVolumeExpansion: true, but shrinking is not supported by common CSI drivers. Size from your actual retention requirement rather than over-provisioning, and make sure expansion is enabled so growing is an option.
Why is my new broker not receiving any data?
Because Kafka does not move existing partitions when you add brokers. New partitions will land on it; existing ones stay where they are. Create a KafkaRebalance resource, review the generated proposal, and approve it. Scaling a Kafka cluster is always two operations.
Do I need Cruise Control?
For any cluster you intend to scale, yes. Without it, partition rebalancing means running Kafka's own reassignment tooling by hand and calculating the plan yourself. Cruise Control generates the plan, shows you its cost before executing, and handles throttling. The two-phase approve-then-execute flow is a feature, not friction.
How do applications connect?
Through the listeners you define on the Kafka resource. The supported types are internal, cluster-ip, nodeport, loadbalancer, route and tlsroute (both OpenShift), plus ingress — which is deprecated, so do not start there. internal listeners are reachable from inside the cluster via a Service that Strimzi creates. For external clients, Strimzi provisions the per-broker addressing Kafka's protocol requires — every broker must be individually addressable, which is why this is more involved than a single Service.
Is Strimzi production-ready?
Yes — it is a CNCF project, widely deployed, and the operator model is mature. The question is not whether Strimzi is ready but whether your team is ready to operate Kafka. Strimzi automates deployment and a good deal of the lifecycle; it does not automate understanding why a partition is under-replicated.
See also
- Kubernetes StatefulSets in Production — the general pattern Strimzi replaces with StrimziPodSet
- Persistent Volumes in Production — StorageClass, binding mode and expansion
- Databases in Kubernetes: Smart Move or Unnecessary Risk? — the same decision, one layer over
- Kafka vs RabbitMQ vs SQS — whether you need Kafka in the first place
Official References
- Apache Kafka documentation — brokers, KRaft mode, topics and consumer groups
- StatefulSets — ordering guarantees, stable identities and update strategies
- StatefulSet basics — a walkthrough of scaling and rolling a stateful workload
Was this article helpful?
Be the first to rate this article
Related Topics
Found this useful? Share it.