Why AI Workloads Blow Up Your Observability Bill — and How to Cap It

Quick answer
GPU spend gets scrutinized line by line. The observability bill that grows right alongside it doesn't — until it lands as a surprise. AI workloads inflate exactly the three axes observability vendors bill on: active series, log volume, and spans. Here's the mechanics of why, and a playbook to cap it.
11 min read · Observability
Everyone scrutinizes the GPU bill. An H100 node isn't cheap, so teams instrument it heavily — every metric, every trace, every prompt logged — to protect the investment. The irony is that this instinct quietly builds a second bill that nobody budgeted for: the observability line item, growing right alongside the GPU spend and often invisible until the annual renewal lands with a number three times larger than last year's.
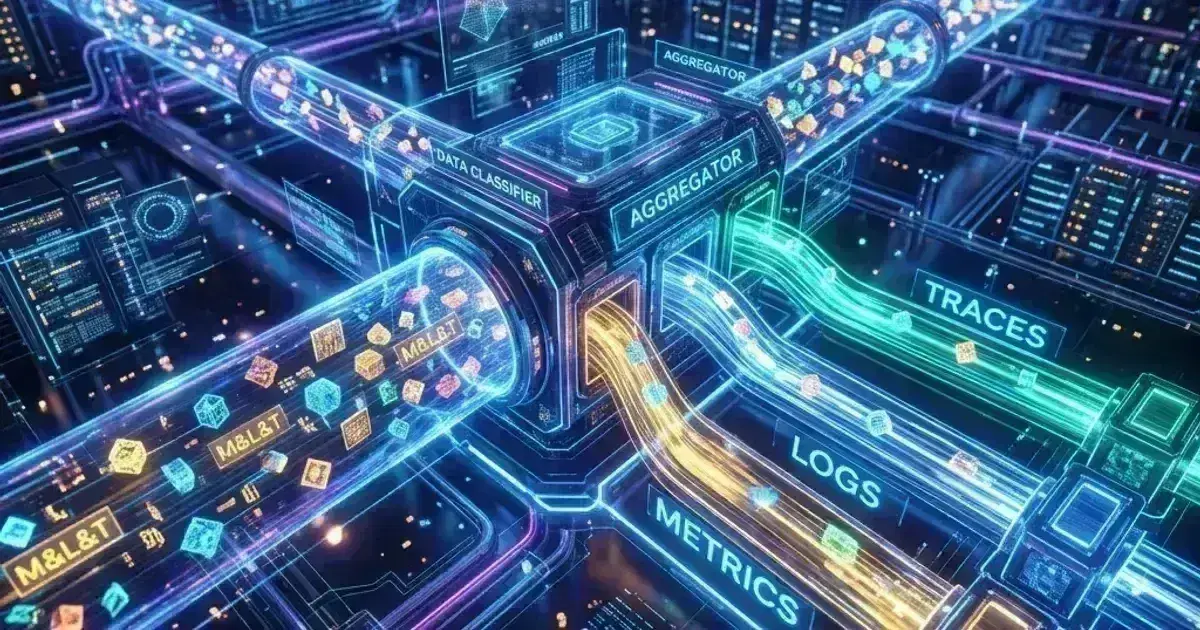
Here's the uncomfortable part: this is not an accident, and it's not your vendor being greedy. AI workloads inflate exactly the three axes observability platforms bill on — active time series (metrics), ingested gigabytes (logs), and spans (traces) — and nothing in the default pipeline pushes back. "Emit everything and figure it out later" was a perfectly reasonable habit when a request was a 200-byte access log and five spans. It does not survive contact with GPU-scale telemetry.
This post is about why AI workloads do this — the actual mechanics, not hand-waving — and a concrete playbook to cap the cost without going blind.
Why AI Telemetry Is Different
A traditional web service emits a predictable, bounded stream of telemetry. An LLM-serving or agentic workload breaks nearly every assumption that made that stream cheap. Five drivers do most of the damage.
1. GPU metrics are dense
The moment you deploy the NVIDIA DCGM exporter — and you should, GPU observability is not optional — you're emitting dozens of metrics per GPU: utilization, memory used/free, temperature, power draw, SM occupancy, NVLink throughput, PCIe traffic, ECC errors, clock speeds, and more. Now multiply:
- by the number of GPUs per node (8 is common),
- by every node in the fleet,
- by MIG partitions if you slice GPUs — each MIG instance is its own labeled set of series,
- by per-process metrics if you enable them (one series per PID per GPU).
A single 8-GPU node can easily contribute thousands of active series before your application emits a single metric.
2. Cardinality explodes at the label level
This is the big one. Metrics cost is driven by active time series, and the number of series is the product of every label's distinct values. LLM serving invites a flood of labels: model, model_version, quantization, adapter / LoRA id, gpu_uuid, tensor_parallel_rank, outcome. Each is reasonable on its own. Multiplied together they detonate.
Then someone adds request_id, user_id, or prompt_id as a label "just for debugging." Those are unbounded — every request creates a brand-new series that lives forever in your index. This single mistake is the most common cause of a runaway metrics bill, and it's almost always avoidable (see the playbook).
3. Per-inference logging is enormous
A normal access log is a couple hundred bytes. An LLM request, logged naively, includes the full prompt and completion — which can be thousands of tokens of text — plus token counts, latencies, and model params. Teams log all of it "for evals" or "for debugging." At even modest QPS, per-inference logging of prompts and completions can dwarf your entire pre-AI log volume. Logs bill by ingested gigabyte; this is a gigabyte firehose.
4. Agent traces are deep, not shallow
A microservice request produces a handful of spans. An agentic request produces hundreds: each tool call, each retrieval step, each chained LLM call, each guardrail check is a span, often nested many levels deep. A single user turn through an agent can generate more spans than a hundred ordinary web requests. Trace-based observability tools bill on spans (or ingested trace volume), and agents turn every interaction into a span factory.
5. The new golden signals are custom histograms
AI workloads have their own SLIs — time-to-first-token (TTFT), inter-token latency (ITL), tokens/sec, KV-cache utilization, queue depth, batch size, GPU memory fragmentation. Teams add them as histograms, per model. That's the right instinct for latency, but a histogram isn't one series — it's one series per bucket. A 12-bucket TTFT histogram, split by model × endpoint × outcome, is not one metric. It's thousands.
The Cardinality Math
Make it concrete. Say you have one TTFT latency histogram with 12 buckets (plus _sum and _count, so ~14 series per combination). You label it by:
model: 8 valuesendpoint: 3 valuesquantization: 3 valuesoutcome: 4 values (success, timeout, oom, error)
That's 8 × 3 × 3 × 4 = 288 label combinations, times ~14 series each = ~4,000 active series from a single histogram. Add a second histogram (ITL), a few counters, and DCGM's per-GPU metrics, and one modest serving deployment is contributing tens of thousands of series. Now add the request_id label someone slipped in, and the number is unbounded.
Most metrics vendors bill on active series or data-points-per-minute. You can see how a bill triples without anyone writing "expensive" anywhere in the code.
The Playbook to Cap It
Good news: nearly all of this is controllable, and none of the fixes require flying blind. They're ordered by leverage — do the first one and you've already won most of the battle.
1. Own the pipeline: put an OpenTelemetry Collector in front of everything
This is the single highest-leverage move, because it decouples what you emit from what you pay for. Applications and exporters send to a Collector you control, and the Collector — not your wallet — decides what actually reaches the vendor. Filtering, sampling, relabeling, aggregation, and routing all happen before the per-GB / per-series meter runs. Without this layer, every optimization below means editing application code; with it, they're pipeline config. Build this first. See the OpenTelemetry instrumentation guide for how the pieces fit.
2. Set a cardinality budget and enforce it in the Collector
Treat active series as a budget, not a free resource. In the Collector's transform/filter processors:
- Drop unbounded labels —
request_id,user_id,prompt_id,trace_id-as-label. These never belong on metrics. - Where you need per-request identity, attach it to a trace and link it with an exemplar, so you can still jump from an aggregate spike to a representative request — without paying for a new series per request.
- Bound the labels that are useful: bucket
sequence_lengthinto ranges instead of raw values.
3. Tail-sample traces — keep the interesting ones, drop the boring ones
You do not need 100% of agent traces. Use tail-based sampling: keep every trace that errored or exceeded a latency threshold, and sample the rest down to a few percent. Crucially, sample at the trace level, not the span level — half a 300-span agent trace is useless. This routinely cuts trace spend by 90%+ while preserving exactly the traces you'd actually open.
4. Keep prompts and completions out of the hot log path
Full prompt/completion text is the log firehose. Split it:
- Hot path (your logging vendor): metadata only — token counts, latencies, model, outcome, and a content hash for correlation.
- Cold path (cheap object storage or a dedicated eval store): the full prompt/completion payloads, if you need them for evals or debugging.
You keep the ability to debug and evaluate; you stop paying premium per-GB logging rates to store megabytes of model chatter.
5. Right-size GPU metrics and use tiered retention
- Scrape DCGM at a sane interval (per-second, retained forever, is almost never needed). Drop per-process and profiling series you don't actually query.
- Use recording rules to pre-aggregate the roll-ups you look at, so dashboards don't re-scan raw series.
- Apply tiered retention: high-resolution for days, downsampled roll-ups for the long tail. Logs full for a week or two, then archived to object storage. Old telemetry at full fidelity is pure cost with near-zero query value.
6. Separate AI product analytics from infra observability
Token usage per customer, cost-per-conversation, eval scores, model-quality trends — this is product and financial analytics, and it does not belong in your Datadog/metrics bill at metrics prices. Route it to a data warehouse or a dedicated LLM-eval platform. Your observability stack should answer "is the service healthy and fast," not "what did each user spend." Conflating the two is a quiet, expensive mistake. For the surrounding cost discipline, see FinOps tooling: Kubecost, Vantage, Infracost.
Observability Cost Control Checklist
Cardinality, retention, sampling, and pipeline checks that keep metrics/logs/traces bills sane. Plain Markdown you can commit to your repo.
Free. Instant download. You'll also get the occasional deep-dive from the newsletter — unsubscribe anytime.
The Takeaway
The AI observability bill is not a mystery and it's not inevitable — it's a predictable consequence of applying cheap-workload habits to expensive-workload telemetry, on a pricing model that rewards exactly that. The fix is not shopping for a cheaper vendor; you'll just hit the same cardinality wall at a slightly lower unit price. The fix is owning your telemetry pipeline and treating cardinality, log volume, and span count as budgets you spend deliberately.
Put an OpenTelemetry Collector in the middle, drop the unbounded labels, sample the traces, keep the prompts out of the hot path, and separate product analytics from infra health. Do that and your observability bill scales with the value you get from telemetry — not with the number of GPUs you happened to turn on.
If you're standing up the GPU platform underneath all this, running GPU and ML workloads on Kubernetes and deploying LLMs on Kubernetes cover the layer this observability sits on top of.
See also
Frequently Asked Questions
Why do AI workloads cost so much more to observe than normal services?
Because they inflate all three axes observability vendors bill on at once. GPU metrics (DCGM) add dozens of dense series per GPU; LLM labels like model, quantization, and adapter multiply metric cardinality; full prompt/completion logging turns each request into kilobytes or megabytes of logs; and agentic requests generate hundreds of trace spans each. A traditional web request touches none of these the same way, so the same instrumentation habits cost an order of magnitude more.
What is the single biggest driver of a runaway metrics bill?
High-cardinality labels — specifically, putting unbounded values like request_id, user_id, or prompt_id on metrics. Every distinct value creates a new active time series that persists in the index, so an unbounded label means unbounded series. Keep per-request identity in traces (linked via exemplars), never in metric labels, and your metrics cardinality stays predictable.
Does an OpenTelemetry Collector actually reduce cost, or just move data around?
It reduces cost, because it lets you sample, filter, drop labels, and aggregate telemetry before it reaches the vendor's meter. Without a Collector, what your code emits equals what you pay for. With one, you decouple the two: applications emit freely, and the Collector enforces your cardinality budget and sampling policy centrally. It's the highest-leverage change you can make.
How do I sample agent traces without losing the ability to debug them?
Use tail-based sampling and decide at the trace level, not the span level. Keep 100% of traces that errored or exceeded a latency threshold, and sample the rest down to a few percent. Because the decision is made per whole trace, you never end up with half a 300-span agent trace — you keep complete, useful traces for exactly the requests worth investigating and drop the routine ones.
Should I stop logging prompts and completions entirely?
No — just keep them out of your expensive hot logging path. Log lightweight metadata (token counts, latencies, model, outcome, a content hash) to your logging vendor, and send the full prompt/completion payloads to cheap object storage or a dedicated eval store. You retain everything you need for debugging and evaluation without paying premium per-gigabyte rates to store large volumes of model text.
For adjacent decisions, see OpenTelemetry Collector on Kubernetes, monitoring strategy: Prometheus vs Datadog, and FinOps tooling for cost control.
Watching your observability bill grow faster than your GPU fleet? Talk to us at Coding Protocols — we help platform teams build telemetry pipelines that scale with value, not with cardinality.
Official References
- OpenTelemetry documentation — the SDK, collector and semantic conventions
- OpenTelemetry Collector configuration — receivers, processors, exporters and pipelines
- AWS Savings Plans — plan types, commitment terms and how discounts apply
- EC2 Spot Instances — interruption behaviour and capacity rebalancing
Was this article helpful?
Be the first to rate this article
Related Topics
Found this useful? Share it.