Prometheus and Grafana on Kubernetes: Production Monitoring Stack
Quick answer
The kube-prometheus-stack Helm chart deploys Prometheus, Alertmanager, Grafana, and all the Kubernetes scrape configs in one operation. Production operation requires more: persistent storage for metrics retention, ServiceMonitor CRDs for application metrics, PrometheusRule CRDs for alerts, and federation or remote write for multi-cluster visibility. This covers the complete setup plus the observability patterns that catch incidents before users do.
- Installation
- ServiceMonitor: Scraping Application Metrics
- PrometheusRule: Custom Alerts
- Alertmanager Configuration
- Recording Rules: Pre-Computed Aggregations
13 min read · Observability
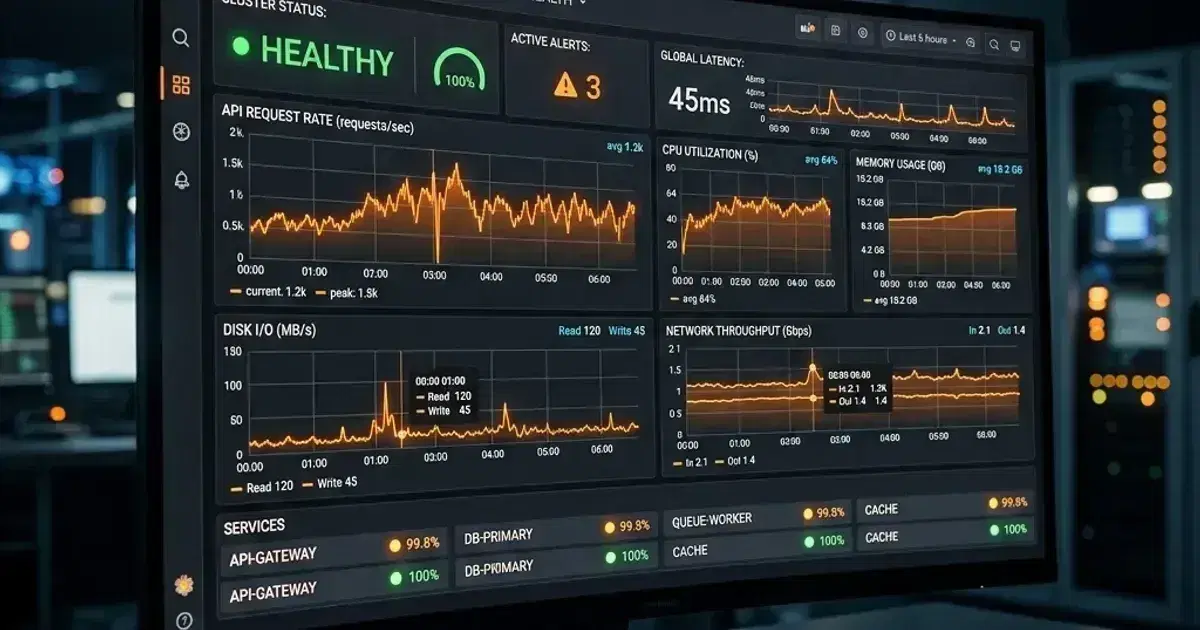
The kube-prometheus-stack installs in minutes and gives you cluster-wide metrics, pre-built Kubernetes dashboards, and a working alerting pipeline immediately. The gap between "installed" and "production-ready" is mostly configuration: persistent storage for metrics history, custom scrape configs for your applications, and alerts tuned to your SLOs rather than the defaults.
This covers the setup through a lens of what matters operationally — not every knob, just the ones that determine whether you get paged at 3 AM or whether Prometheus fills up a node's disk.
Installation
1helm repo add prometheus-community https://prometheus-community.github.io/helm-charts
2helm repo update
3
4helm install kube-prometheus-stack prometheus-community/kube-prometheus-stack \
5  --namespace monitoring \
6  --create-namespace \
7  --version 90.0.0 \
8 --values prometheus-values.yaml1# prometheus-values.yaml
2prometheus:
3 prometheusSpec:
4 # Retention and storage
5 retention: 30d
6 retentionSize: "50GB" # Stop accepting new data when this limit is hit
7 storageSpec:
8 volumeClaimTemplate:
9 spec:
10 storageClassName: gp3
11 accessModes: ["ReadWriteOnce"]
12 resources:
13 requests:
14 storage: 100Gi # 100Gi for 30d retention on a medium cluster
15
16 # Resource limits (adjust for cluster size)
17 resources:
18 requests:
19 cpu: 500m
20 memory: 2Gi
21 limits:
22 cpu: 2000m
23 memory: 8Gi
24
25 # Let Prometheus discover ServiceMonitors and PrometheusRules across all namespaces
26 serviceMonitorNamespaceSelector: {} # All namespaces
27 serviceMonitorSelector: {} # All ServiceMonitors
28 ruleNamespaceSelector: {}
29 ruleSelector: {}
30
31 # Scrape interval
32 scrapeInterval: 30s
33 evaluationInterval: 30s
34
35alertmanager:
36 alertmanagerSpec:
37 storage:
38 volumeClaimTemplate:
39 spec:
40 storageClassName: gp3
41 resources:
42 requests:
43 storage: 5Gi
44
45grafana:
46 enabled: true
47 persistence:
48 enabled: true
49 storageClassName: gp3
50 size: 10Gi
51
52 # Configure Grafana admin credentials via a Kubernetes Secret
53 admin:
54 existingSecret: grafana-admin-secret # Secret must contain adminUser and adminPassword keys
55 userKey: admin-user
56 passwordKey: admin-password
57
58 # Ingress for Grafana
59 ingress:
60 enabled: true
61 ingressClassName: nginx
62 annotations:
63 cert-manager.io/cluster-issuer: letsencrypt-prod
64 hosts: [grafana.codingprotocols.com]
65 tls:
66 - secretName: grafana-tls
67 hosts: [grafana.codingprotocols.com]ServiceMonitor: Scraping Application Metrics
ServiceMonitor is the CRD that tells Prometheus which Services to scrape:
1apiVersion: monitoring.coreos.com/v1
2kind: ServiceMonitor
3metadata:
4  name: payments-api
5  namespace: payments
6  labels:
7    app: payments-api    # Must match serviceMonitorSelector if configured
8spec:
9  selector:
10    matchLabels:
11      app: payments-api    # Matches the Service
12
13  endpoints:
14    - port: metrics          # Named port on the Service (not port number)
15      path: /metrics
16      interval: 30s
17      scheme: http
18
19  namespaceSelector:
20    matchNames:
21      - payments    # Only scrape from the payments namespace
The Service must expose a named port:
1apiVersion: v1
2kind: Service
3metadata:
4  name: payments-api
5  namespace: payments
6  labels:
7    app: payments-api
8spec:
9  selector:
10    app: payments-api
11  ports:
12    - name: http
13      port: 8080
14    - name: metrics     # ServiceMonitor references this name
15      port: 9090        # Dedicated metrics port (or same as http if /metrics is on main port)
For a deeper look at ServiceMonitor selectors, PodMonitor, AlertmanagerConfig, PrometheusRule validation, and multi-namespace RBAC patterns, see Prometheus Operator: ServiceMonitor, AlertManager, and Production Monitoring.
PrometheusRule: Custom Alerts
1apiVersion: monitoring.coreos.com/v1
2kind: PrometheusRule
3metadata:
4  name: payments-api-alerts
5  namespace: payments
6  labels:
7    app: payments-api
8spec:
9  groups:
10    - name: payments-api
11      interval: 30s
12      rules:
13        # SLO: 99.9% success rate — alert when error rate exceeds 0.1%
14        - alert: PaymentsAPIHighErrorRate
15          expr: |
16            sum(rate(http_requests_total{namespace="payments", status=~"5.."}[5m]))
17            /
18            sum(rate(http_requests_total{namespace="payments"}[5m]))
19            > 0.001
20          for: 5m    # Must be elevated for 5 minutes before alerting
21          labels:
22            severity: critical
23            team: payments
24          annotations:
25            summary: "Payments API error rate {{ $value | humanizePercentage }} (threshold: 0.1%)"
26            runbook: "https://runbooks.codingprotocols.com/payments-high-error-rate"
27
28        # SLO: P99 latency < 500ms
29        - alert: PaymentsAPIHighLatency
30          expr: |
31            histogram_quantile(0.99,
32              sum(rate(http_request_duration_seconds_bucket{namespace="payments"}[5m]))
33              by (le)
34            ) > 0.5
35          for: 10m
36          labels:
37            severity: warning
38            team: payments
39          annotations:
40            summary: "Payments API P99 latency {{ $value | humanizeDuration }} (threshold: 500ms)"
41
42        # Capacity: alert when pod count drops below expected
43        - alert: PaymentsAPIDeploymentReplicas
44          expr: |
45            kube_deployment_status_replicas_available{namespace="payments", deployment="payments-api"} < 2
46          for: 5m
47          labels:
48            severity: critical
49            team: payments
50          annotations:
51            summary: "Payments API has fewer than 2 available replicas"
Observability Cost Control Checklist
Cardinality, retention, sampling, and pipeline checks that keep metrics/logs/traces bills sane. Plain Markdown you can commit to your repo.
Free. Instant download. You'll also get the occasional deep-dive from the newsletter — unsubscribe anytime.
Alertmanager Configuration
1# alertmanager-config.yaml — configure routing and receivers
2apiVersion: monitoring.coreos.com/v1
3kind: AlertmanagerConfig
4metadata:
5  name: payments-alerts
6  namespace: payments
7spec:
8  route:
9    receiver: payments-slack
10    groupBy: [alertname, namespace]
11    groupWait: 30s
12    groupInterval: 5m
13    repeatInterval: 4h
14    routes:
15      - receiver: payments-pagerduty
16        matchers:
17          - name: severity
18            value: critical
19        continue: false    # Don't also send to Slack if PagerDuty matched
20
21  receivers:
22    - name: payments-slack
23      slackConfigs:
24        - apiURL:
25            name: slack-webhook-secret    # Secret in same namespace
26            key: webhook-url
27          channel: "#payments-alerts"
28          title: "{{ .GroupLabels.alertname }}"
29          text: "{{ range .Alerts }}{{ .Annotations.summary }}\n{{ end }}"
30
31    - name: payments-pagerduty
32      pagerdutyConfigs:
33        - routingKey:
34            name: pagerduty-secret
35            key: routing-key
36          description: "{{ .GroupLabels.alertname }}: {{ .CommonAnnotations.summary }}"
Recording Rules: Pre-Computed Aggregations
For expensive queries that are evaluated frequently (dashboards, multi-step alert expressions), recording rules pre-compute them:
1spec:
2  groups:
3    - name: payments-api-recording
4      rules:
5        # Pre-compute request rate per status code — expensive query used in 3 alerts
6        - record: payments:http_requests:rate5m
7          expr: |
8            sum(rate(http_requests_total{namespace="payments"}[5m])) by (status, method, path)
9            # Warning: if 'path' contains dynamic segments (UUIDs, user IDs), this creates unbounded cardinality. Normalize paths before aggregating.
10
11        # Pre-compute error ratio — used in SLO dashboard
12        - record: payments:error_ratio:rate5m
13          expr: |
14            sum(rate(http_requests_total{namespace="payments", status=~"5.."}[5m]))
15            /
16            sum(rate(http_requests_total{namespace="payments"}[5m]))
Recording rules are evaluated on the Prometheus scrape interval and stored as new time series. Subsequent queries hit the pre-computed series instead of re-scanning raw metrics.
Remote Write: Multi-Cluster and Long-Term Storage
For clusters with multiple Prometheus instances, or for long-term metric storage beyond Prometheus's local retention:
1prometheusSpec:
2  remoteWrite:
3    - url: "https://aps-workspaces.us-east-1.amazonaws.com/workspaces/ws-xxx/api/v1/remote_write"
4      sigv4:
5        region: us-east-1
6      queueConfig:
7        maxSamplesPerSend: 1000
8        batchSendDeadline: 5s
AWS Managed Service for Prometheus (AMP) accepts remote write and provides indefinite retention, multi-cluster aggregation, and native IAM access control. The sigv4 section signs requests using the Prometheus pod's IRSA role.
Edge Monitoring: Prometheus Agent Mode
In 2026, for edge clusters or development environments, we often use Prometheus Agent Mode. This mode disables the local TSDB and Alertmanager, turning Prometheus into a lightweight scraping engine that remote-writes all data to a central backend:
prometheusSpec:
  agentMode: true    # Disables local storage and alerting
  remoteWrite:
    - url: "https://aps-workspaces.us-east-1.amazonaws.com/workspaces/ws-xxx/api/v1/remote_write"
      sigv4:
        region: us-east-1
Agent mode significantly reduces memory overhead and simplifies operations for clusters that don't need local data retention or complex local alerting.
Important: In Agent mode, the local TSDB and alerting engine are disabled. PrometheusRule CRDs are silently ignored — configure alerting at your remote backend (Amazon Managed Prometheus, Thanos Ruler, etc.) instead.
Key Kubernetes Metrics to Alert On
Beyond application-level metrics, these Kubernetes metrics cover the infrastructure layer:
1# Node memory pressure — node close to OOM eviction
2node_memory_MemAvailable_bytes / node_memory_MemTotal_bytes < 0.10
3
4# PVC close to full — storage running out
5(kubelet_volume_stats_capacity_bytes - kubelet_volume_stats_available_bytes) /
6kubelet_volume_stats_capacity_bytes > 0.85
7
8# Pods not ready
9kube_pod_status_ready{condition="false"} == 1
10
11# Deployment generation mismatch (stuck rollout)
12# for: 5m — prevents firing transiently during normal rollouts
13kube_deployment_status_observed_generation != kube_deployment_metadata_generation
14
15# Container OOM kills (pods terminated due to OOM)
16kube_pod_container_status_last_terminated_reason{reason="OOMKilled"} == 1
17
18# API server error rate
19sum(rate(apiserver_request_total{code=~"5.."}[5m])) /
20sum(rate(apiserver_request_total[5m])) > 0.01
See also
- Install Prometheus and Grafana on Kubernetes with kube-prometheus-stack
- Monitoring Kubernetes with Prometheus and Grafana
- Build an MCP Server for Prometheus
Frequently Asked Questions
How do I size Prometheus storage?
Rough formula: (bytes_per_sample × scrape_frequency × time_series_count × retention_days) / compression_ratio. A medium EKS cluster (50 nodes, 500 pods, 100k time series) scraping every 30s generates roughly 15-20GB/month. For 30-day retention: 60GB is a safe starting point. Use retentionSize as a circuit breaker so Prometheus doesn't fill the disk.
Why aren't my ServiceMonitors being picked up?
The Prometheus Operator watches for ServiceMonitor objects with labels matching serviceMonitorSelector. If serviceMonitorSelector: {} (empty) is not set, only ServiceMonitors with specific labels are picked up. Check: kubectl describe prometheus -n monitoring — the serviceMonitorSelector field shows what's being selected. Also verify the ServiceMonitor's namespace is included in serviceMonitorNamespaceSelector.
Should I use Thanos or VictoriaMetrics for long-term storage?
For EKS, AWS Managed Prometheus (AMP) is the simplest path — no additional components to operate, native IAM, and it handles federation. For multi-cloud or on-premises, Thanos (sidecar mode + object storage) or VictoriaMetrics (cluster mode) are both production-proven. Thanos adds ~3-5 components and operational overhead; VictoriaMetrics is simpler to operate. If you're already heavily AWS, AMP first.
For the observability hub covering Prometheus, Grafana, and OpenTelemetry together, see Kubernetes Observability: Prometheus, Grafana, and OpenTelemetry in Production. For a unified telemetry pipeline that routes OTLP metrics alongside Prometheus metrics, see OpenTelemetry Collector: Unified Telemetry Pipeline for Kubernetes. For Alertmanager routing and PagerDuty/Slack integrations in depth, see SLOs, Error Budgets, and Burn Rate Alerts. For distributed tracing to complement metrics, see OpenTelemetry: Migrating from Vendor Agents to the Collector.
Setting up observability for a new EKS cluster or migrating from a legacy monitoring stack? Talk to us at Coding Protocols — we help platform teams build monitoring stacks that give developers the metrics they need without drowning on-call in noise.
Official References
- PromQL basics — selectors, functions and rate/increase semantics
- Alertmanager configuration — routing trees, inhibition and receivers
- Grafana documentation — dashboards, panels, variables and provisioning
Was this article helpful?
Be the first to rate this article
Related Topics
Found this useful? Share it.