AWS Elastic Beanstalk Cluster Mode: EKS Without Writing YAML

Quick answer
Beanstalk's new Cluster Mode runs your app on a shared, AWS-managed EKS cluster instead of dedicated EC2 instances — powered by the same EKS Auto Mode compute layer we've covered before. The deploy experience gets simpler; the constraints are real, and some of them are permanent.
- How environments actually end up on a cluster
- The config surface is new, and none of your old options apply
- What you permanently lose, not just what changes
- Clusters get deleted quietly, on a clock
- Where it fits, and where Standard mode still wins
8 min read · AWS
AWS Elastic Beanstalk Cluster Mode: EKS Without Writing YAML
AWS announced Cluster Mode for Elastic Beanstalk on September 17, 2026 — a new environment type that runs your application as containers on an Amazon EKS cluster instead of on dedicated EC2 instances. It's generally available now, in every region where Elastic Beanstalk operates.
The pitch is straightforward: you give Elastic Beanstalk source code, a Dockerfile, or a container image, and it builds, deploys, scales, and patches the environment underneath it. What's actually new here isn't containers-on-Beanstalk — that's been possible for years. It's that the compute layer is now a shared, AWS-managed EKS cluster rather than one Auto Scaling group per environment, and the node capacity comes from EKS Auto Mode — the same node-provisioning model we covered for GPU workloads a few weeks ago. If you've read that piece, a lot of Cluster Mode's actual behavior — the lifecycle you don't control, the things you can't SSH into — should already feel familiar, because it's the identical trade.
How environments actually end up on a cluster
This is the part the announcement glosses over and the part worth understanding before you use it in production: your VPC subnets, not your application, determine which cluster you land on.
Elastic Beanstalk groups Cluster Mode environments onto EKS clusters by the exact set of subnets they use. Two environments in the same AWS account using the same subnet set run on the same cluster, full stop — there's no environment-level opt-out. Use a different subnet set and you get a different cluster. The first environment created with a given subnet set triggers real cluster creation — a CloudFormation stack named beanstalk-cluster-{uuid}, which takes about ten minutes. Every later environment with matching subnets just gets scheduled onto the existing cluster; you never see that ten-minute wait again unless you introduce a new subnet combination.
You don't choose the Kubernetes version. Elastic Beanstalk picks the newest version it supports at cluster creation time, and that version is fixed for the life of the cluster — every environment sharing it inherits that same fixed version, forever, until the cluster itself is deleted and recreated. There's no in-place upgrade path exposed to you.
Two more decisions are locked in at creation and cannot be changed afterward: the subnets, and the IAM roles (cluster role, node role, and the observability role you supply). Try to change any of them on an existing environment and Elastic Beanstalk rejects the update outright:
Changes to EKS cluster configuration (subnets and IAM roles) are not currently supported for an existing environment. Please revert these option settings to continue.
The documented workaround is to create a brand-new environment with the settings you actually want, then swap the two environments' CNAMEs — the same blue/green pattern Beanstalk has always used for other irreversible changes. Decide your subnets and roles like you're deciding them for good, because functionally, you are.
The config surface is new, and none of your old options apply
Standard Beanstalk (the EC2-based environment type, still very much alive) configures scaling and deployment through the classic aws:autoscaling:* and aws:elasticbeanstalk:command namespaces. None of that carries over. Cluster Mode has its own namespace tree, aws:elasticbeanstalk:eks:*, and the two are not interchangeable — a Standard environment's saved configuration template won't apply cleanly to a Cluster environment.
A representative real config, straight from the docs, setting the request port, memory, replica bounds, and rollout behavior:
1aws elasticbeanstalk update-environment \
2    --environment-name my-cluster-env \
3    --option-settings \
4        Namespace=aws:elasticbeanstalk:eks:environment,OptionName=service-port,Value=8080 \
5        Namespace=aws:elasticbeanstalk:eks:environment,OptionName=memory,Value=1Gi \
6        Namespace=aws:elasticbeanstalk:eks:environment,OptionName=load-balancer-type,Value=ALB \
7        Namespace=aws:elasticbeanstalk:eks:environment:autoscaling,OptionName=min-replica,Value=3 \
8        Namespace=aws:elasticbeanstalk:eks:environment:autoscaling,OptionName=max-replica,Value=3 \
9        Namespace=aws:elasticbeanstalk:eks:environment:deployment,OptionName=strategy,Value=RollingUpdate \
10        Namespace=aws:elasticbeanstalk:eks:environment:deployment:strategy:rolling,OptionName=max-surge,Value=25% \
11        Namespace=aws:elasticbeanstalk:eks:environment:deployment:strategy:rolling,OptionName=max-unavailable,Value=0
A few things worth noticing in that example: memory uses Kubernetes quantity notation (1Gi, 512Mi) — this is the first place a Beanstalk user has ever had to know what a Kubernetes quantity is. The strategy option accepts RollingUpdate or Recreate; the console just relabels these as "rolling" and "all at once" so it doesn't have to say Kubernetes out loud. And there's no aws:autoscaling:asg instance count anywhere — because you're not scaling instances, you're scaling replicas, bounded by min-replica/max-replica, while EKS Auto Mode decides how many actual nodes that needs.
AWS Cost & Architecture Review Checklist
The questions we ask in a paid AWS review — rightsizing, storage classes, network egress, and the usual five-figure surprises. Plain Markdown.
Free. Instant download. You'll also get the occasional deep-dive from the newsletter — unsubscribe anytime.
What you permanently lose, not just what changes
Local disk is gone. Every replica's local storage is ephemeral and disappears on restart. If your app writes uploads, session files, or caches to disk and expects them to survive a redeploy, it's incompatible without bolting on external storage (S3, EFS, a database) — this isn't a config flag you flip, it's an architectural requirement you build around before you migrate.
Per-instance health reporting is gone. Standard Beanstalk's host manager reports health per EC2 instance. Cluster Mode doesn't expose per-instance health at all — with an ALB, you get the load balancer's request-rate, error-rate, and latency metrics rolled up at the environment level; with load-balancer-type=None, you don't even get that. If your on-call runbook currently starts with "check which instance is unhealthy," that instance-level view doesn't exist here.
Host access is gone, same as it is on plain EKS Auto Mode. No SSH, no host-level debugging, no DaemonSet writing to the node filesystem. kubectl debug replaces "SSH into the box," and that's a real workflow change for a team that's never touched Kubernetes before — which is exactly who Beanstalk has historically served.
Cluster maintenance is real and reversible only by conforming to it. Elastic Beanstalk continuously verifies that a cluster it created still matches its expected configuration, and applies its own add-on version updates through that same verification. If something modifies the cluster's underlying infrastructure directly — outside of Elastic Beanstalk's own operations — the service detects the mismatch, calls it drift, and reports it plainly in the environment's events: Cluster drift detected for environment '{name}'. {what changed}. Service will skip cluster maintenance for this environment. While drifted, no new environments get placed on that cluster, service-managed updates (including add-on version bumps) stop, and updates to environments already running on it start failing outright. Recovery means reverting whatever caused the mismatch — the event tells you what changed — and retrying. This is the cost of "AWS manages the cluster for you": it only manages a cluster that looks exactly like the one it expects, and it will not silently reconcile drift on your behalf like Terraform would.
Clusters get deleted quietly, on a clock
Terminate the last environment on a cluster, and Elastic Beanstalk schedules cluster deletion for three hours later — not immediately. If you create another environment using the same subnet set within that window, the pending cleanup is cancelled and the existing cluster gets reused instead of tearing down and rebuilding. That's a sensible default for a team iterating quickly, but it means "terminate environment" and "cluster gone" are not the same event, and cost teardown you expect to be instant isn't.
Where it fits, and where Standard mode still wins
Cluster Mode isn't replacing Standard mode — the two run side by side, and AWS is explicit that migration is opt-in per environment, at whatever pace an organization wants. Their own guidance on when Standard remains the better fit lines up with what the architecture above implies:
- Single application, single environment. Sharing a cluster only pays off once you have several environments to share it with — one environment alone is paying for an EKS control plane it doesn't need to.
- Windows / .NET Framework on IIS. Not supported; Cluster Mode's supported platforms are Java, .NET (Core), Python, Node.js, PHP, Ruby, and Go.
- Anything that can't be containerized, or that genuinely needs writable local disk to survive a restart.
- Low-spend workloads. AWS's own framing puts roughly $500/month in total workload spend as the point below which the EKS control-plane fee becomes overhead rather than a rounding error. Below that, EC2-based Standard mode is very likely cheaper in practice — Cluster Mode adds no Beanstalk-level charge of its own, but you're still paying for the EKS control plane, Auto Mode compute, ECR storage, and CloudWatch, none of which are Free Tier eligible.
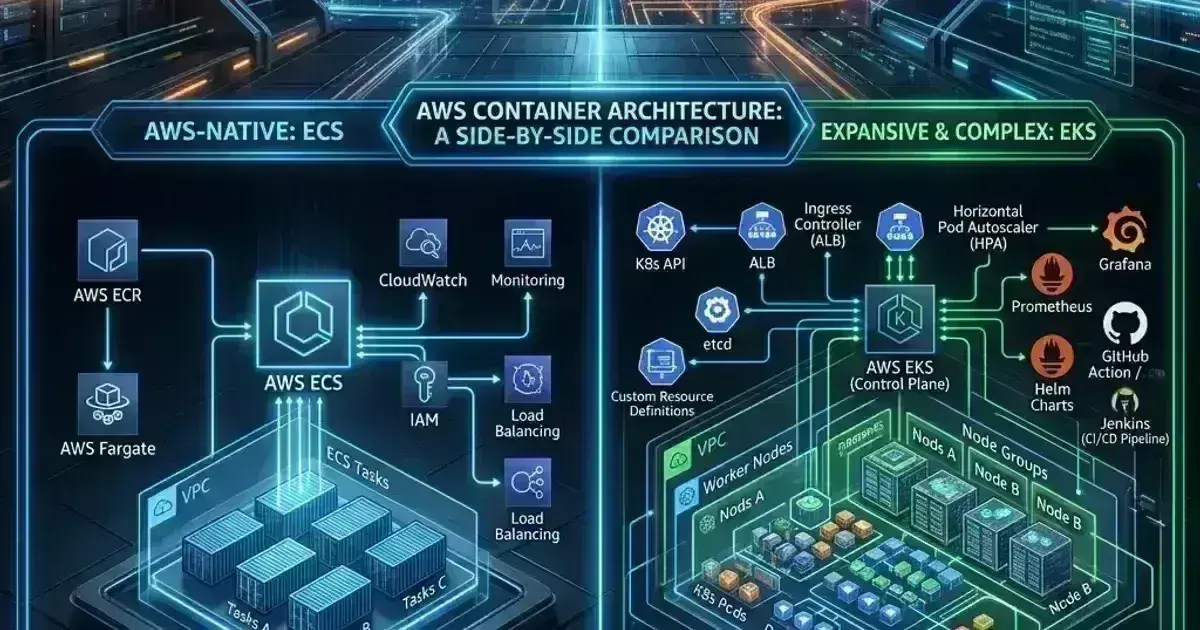
Where it's a genuine win is the shape of workload Beanstalk has always targeted: a handful of stateless web services or APIs, previously each burning a dedicated Auto Scaling group even at low, spiky traffic, now consolidated onto shared, AWS-patched infrastructure with production deployment strategies (rolling, immutable, all-at-once, traffic-splitting with automatic rollback) built in rather than hand-rolled. If that's your actual portfolio shape, the EKS knowledge this normally demands is exactly what Elastic Beanstalk is now absorbing on your behalf — for a container-shaped, stateless, non-Windows app, this is a legitimately easier path onto EKS than choosing between EKS and ECS yourself and building the operational tooling around either one from scratch. Just don't mistake "managed" for "unconstrained" — every constraint above is real, and several of them — the Kubernetes version, the subnets, the IAM roles — are ones you only get to decide once.
Was this article helpful?
Be the first to rate this article
Related Topics
Found this useful? Share it.