What Is a Service Mesh? Sidecars, mTLS, and Traffic Control Explained

Quick answer
A service mesh is a dedicated infrastructure layer that manages service-to-service communication through proxies — adding mTLS, traffic control, resilience, and observability without touching application code. Here's how it works and whether you actually need one.
9 min read · Kubernetes
A service mesh is a dedicated infrastructure layer that manages communication between the services in your application. Instead of each service handling encryption, retries, load balancing, and metrics in its own code, the mesh moves all of that into a network of proxies that sit alongside your services. The result: you get mutual TLS, traffic control, resilience, and deep observability across every service-to-service call — without changing application code. It's most closely associated with Kubernetes, but the concept applies anywhere you run many small services that talk to each other.
How a service mesh works
Every service mesh splits into two halves: a data plane that moves the traffic, and a control plane that decides how.
The data plane is a fleet of lightweight network proxies. In the classic model, one proxy is injected next to each application container as a sidecar — a separate process in the same Kubernetes pod. Your app thinks it's talking directly to another service, but every request actually goes out through its local proxy, across the network to the destination's proxy, and only then to the destination app. Because the proxy intercepts both sides of every call, it can encrypt traffic, enforce policy, retry failures, and record metrics — all transparently. Istio's classic mode uses Envoy as this sidecar; Linkerd ships its own purpose-built micro-proxy written in Rust.
The control plane is the brain. It doesn't touch request traffic itself; instead it configures the proxies. You declare intent — "encrypt all traffic in this namespace," "send 5% of requests to v2," "retry failed calls twice" — and the control plane translates that into proxy configuration and pushes it out. It also issues and rotates the TLS certificates that make mutual TLS work, and aggregates telemetry from the proxies.
The sidecar model is powerful but not free. Running a proxy next to every pod adds CPU, memory, and a little latency to every hop, and it doubles your container count. That cost is what's driving the big 2026 shift toward sidecarless meshes:
- Istio ambient mode replaces per-pod sidecars with a per-node proxy (ztunnel) for L4 traffic — mTLS and identity — and adds optional L7 "waypoint" proxies only where you need advanced routing. You pay for the heavy proxy only when you use it.
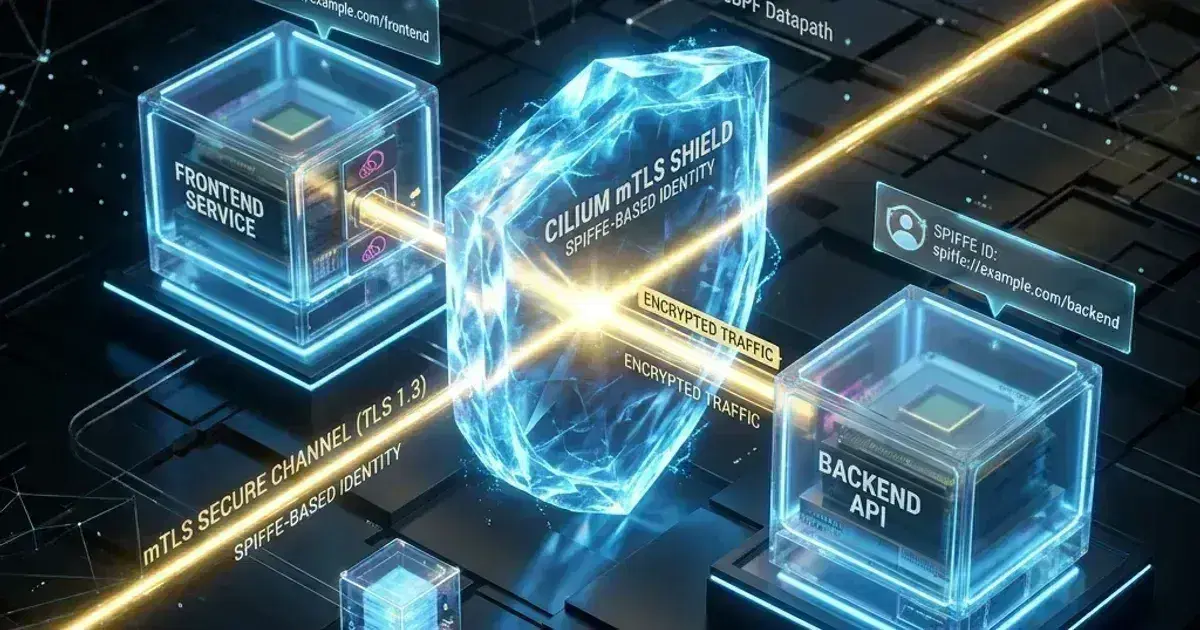
- Cilium pushes mesh functions into the Linux kernel itself using eBPF, avoiding a userspace proxy for much of the path. It can even provide mutual authentication and identity without a full service mesh.
The trade-off is the same either way: sidecars give you the richest per-workload L7 features at higher overhead; sidecarless/eBPF approaches cut resource cost and operational sprawl but historically offered thinner L7 capabilities. In 2026 that gap is closing fast.
What it gives you
The whole point of a mesh is to solve cross-cutting networking problems once, in the platform, instead of once per service in every language you run. The four big capabilities:
Mutual TLS (mTLS) and zero-trust identity. The mesh gives every workload a cryptographic identity and automatically encrypts and authenticates every service-to-service connection. You get zero-trust networking — no service trusts another just because they share a network — with automatic certificate issuance and rotation. Nobody writes TLS code; nobody manages certs by hand.
Traffic management. Because proxies mediate every request, the mesh can route with surgical precision: shift 1% of traffic to a canary, do blue-green cutovers, mirror production traffic to a test version, or split by HTTP header. This is the foundation for progressive delivery, and it pairs naturally with tools like Argo Rollouts.
Resilience. Retries, timeouts, circuit breaking, and rate limiting move out of application code and into the mesh, applied consistently everywhere. A misbehaving downstream service gets isolated before it cascades into an outage.
Observability. Since the proxies see every request, the mesh emits uniform golden-signal metrics (latency, traffic, errors, saturation), distributed traces, and a live service dependency map — for every service, with no manual instrumentation. For many teams this is the single biggest reason to adopt one.
Kubernetes Production Readiness Checklist
The pre-launch checks we run before calling a cluster production-ready — probes, resources, RBAC, upgrades, and backups. Plain Markdown you can commit to your repo.
Free. Instant download. You'll also get the occasional deep-dive from the newsletter — unsubscribe anytime.
Do you actually need one?
Honestly? Often not — at least not yet. A service mesh solves problems that only get painful at a certain scale, and it introduces real cost of its own.
You probably don't need a mesh if:
- You run a handful of services, or a monolith plus a few helpers. The complexity a mesh manages simply isn't there.
- Your encryption and observability needs are already met by an ingress/gateway, a TLS-terminating load balancer, and per-language libraries.
- You don't have someone who can own the mesh operationally. A mesh is a distributed system in its own right — control plane upgrades, proxy version skew, certificate lifecycles, and debugging "why is this request failing" through an extra network hop are all real work.
A mesh starts to earn its keep when:
- You have dozens or hundreds of services across multiple languages, and re-implementing mTLS, retries, and metrics in each one is untenable.
- You need zero-trust mTLS everywhere for compliance, and doing it in-app is error-prone.
- You want progressive delivery (canary, traffic mirroring) as a standard platform capability.
- You need consistent, uniform observability that you can't get by instrumenting every service by hand.
The honest framing: a mesh trades application-code complexity for platform complexity. That's a good trade at scale and a bad one for a small system. If you only need one capability — say, encrypted internal traffic — reach for the narrowest tool first. Cilium's eBPF-based approach or the Kubernetes Gateway API can cover a lot of ground before you take on a full mesh.
Common misconceptions
"A service mesh is just an API gateway." No. A gateway handles north-south traffic — requests entering your cluster from outside. A mesh handles east-west traffic — the internal chatter between your own services. They're complementary, not interchangeable; many clusters run both.
"A service mesh will slow everything down." Sidecars do add a small per-hop latency and resource overhead, but for most workloads it's single-digit milliseconds, and sidecarless/eBPF modes shrink it further. The bigger risk isn't raw latency — it's operational overhead if no one owns the mesh.
"Installing a mesh means rewriting my apps." The opposite is the selling point: the mesh is transparent to application code. You get mTLS and metrics without touching your services. (You do write mesh configuration, and you may tune apps to play nicely with retries and timeouts.)
"A mesh replaces my observability stack." It generates excellent network-level telemetry, but it doesn't know your business logic. You still want application-level tracing and metrics; the mesh complements them.
"Service mesh means Istio." Istio is the most feature-rich option, but Linkerd is dramatically simpler to operate, and Cilium, Consul, and Kuma all exist. The right choice depends on how much you value features versus operational simplicity.
Frequently Asked Questions
What is the difference between the data plane and the control plane?
The data plane is the set of proxies that actually carry your traffic and enforce policy on each request. The control plane is the management layer that configures those proxies, issues certificates, and collects their telemetry. The control plane never sits in the request path — if it goes down, existing traffic keeps flowing on the last-known proxy configuration.
Do I need Kubernetes to run a service mesh?
No, but it's the natural home. Kubernetes' pod model makes sidecar injection clean, and most meshes are built Kubernetes-first. Istio and Consul can extend to VMs and bare metal, so you can mesh workloads outside the cluster, but the smoothest experience by far is on Kubernetes.
What is a sidecar, and why are meshes moving away from it?
A sidecar is a proxy container injected next to each application container in the same pod, intercepting all its traffic. It gives you rich per-workload control but adds a proxy — with its CPU, memory, and latency — to every single pod. Sidecarless approaches like Istio's ambient mode and Cilium's eBPF datapath deliver the same identity and encryption with far less overhead, which is why they're the direction of travel in 2026.
Is a service mesh the same as mTLS?
No. mTLS (mutual TLS) is one feature a service mesh provides — automatic, mutually authenticated encryption between services. A mesh bundles mTLS with traffic management, resilience, and observability. You can get mTLS without a full mesh (for example via Cilium or SPIFFE/SPIRE directly), but a mesh makes it the default with zero app changes.
Should a small team adopt a service mesh?
Usually not right away. If you run a few services, the operational cost of a mesh outweighs the benefit — start with an ingress/gateway and per-language libraries. Adopt a mesh when service count, multi-language sprawl, or compliance-driven zero-trust requirements make solving these problems per-service impractical. When you do, start with the simplest tool that meets the need.
See also
- Istio Service Mesh on Kubernetes: mTLS, Traffic Management, and Observability — a hands-on deep dive into the most feature-rich mesh.
- Service Mesh Showdown: Istio vs Linkerd in 2026 — how the two leading meshes compare on features and operational cost.
- Cilium Mutual Authentication: mTLS Without a Service Mesh — the sidecarless, eBPF-native path to encrypted service identity.
Not sure whether a service mesh is the right call for your platform? Talk to us at Coding Protocols — we'll help you weigh the operational cost against the payoff and pick the narrowest tool that solves your actual problem.
Official References
- Init Containers — ordering, restart behaviour and resource accounting
- Istio traffic management — VirtualService, DestinationRule and gateway routing
- Linkerd architecture — control plane and proxy responsibilities
- SPIFFE overview — SVIDs, trust domains and workload attestation
Was this article helpful?
Be the first to rate this article
Related Topics
Found this useful? Share it.