Kubernetes Resource Management: Requests, Limits, QoS, and LimitRanges
Quick answer
Resource requests tell the scheduler how much CPU and memory a pod needs. Resource limits cap what the pod can use. The gap between them determines the pod's Quality of Service class, which controls eviction order during node pressure. Getting requests and limits wrong causes OOM kills at peak load, CPU throttling that looks like application slowness, and pods being scheduled onto nodes that can't support them. This covers the mechanics of CPU throttling, OOM behavior, QoS classes, LimitRanges for namespace defaults, ResourceQuotas for multi-tenant capacity management, and how VPA handles automatic right-sizing.
- CPU Throttling
- Memory: OOM Kills
- Quality of Service Classes
- LimitRange: Namespace Defaults
- ResourceQuota: Namespace Capacity Limits
13 min read · Platform Engineering
Two numbers control how much compute a Kubernetes pod gets: requests (what the scheduler reserves on the node) and limits (the maximum the container can consume). The difference between them is subtle and frequently misunderstood:
- CPU requests are soft guarantees. A pod requesting 500m CPU on a 4-CPU node gets at least 500m when the node is contended. When the node has spare capacity, the pod can burst above its request — up to its limit.
- Memory requests are also soft scheduling guarantees. But memory isn't compressible: when a container exceeds its memory limit, the kernel OOM-kills the process. There is no equivalent of CPU throttling for memory.
These two mechanisms create fundamentally different failure modes that are easy to confuse in production.
CPU Throttling
When a container's CPU usage exceeds its cpu.limits, the Linux CFS (Completely Fair Scheduler) throttles it — the container gets no CPU time for the remainder of the scheduling period (100ms by default). From inside the container, application code continues running but takes longer. From the outside, the application appears slow.
CPU throttling is invisible in pod metrics unless you're watching the right metrics:
1# CPU throttling ratio — fraction of CPU time being throttled
2sum by (pod, container) (
3  rate(container_cpu_cfs_throttled_periods_total{namespace="payments"}[5m])
4) /
5sum by (pod, container) (
6  rate(container_cpu_cfs_periods_total{namespace="payments"}[5m])
7)
A ratio above 0.25 (25% of CPU time throttled) typically causes noticeable latency. Values above 0.5 indicate the CPU limit is significantly undersized.
The burstable CPU pattern: Set requests to the steady-state CPU usage. Set limits high (2-4x requests) or leave them unset if you can accept noisy-neighbor risk. Tight CPU limits (limit == request) provide isolation but cause throttling during legitimate bursts. For latency-sensitive services, either eliminate CPU limits entirely (accept noisy-neighbor) or set them high enough to never throttle (test under load).
Memory: OOM Kills
When a container exceeds its memory limit, the kernel sends SIGKILL to the container process. In Kubernetes, this shows as:
1kubectl get pod payments-api-<hash> -n payments
2# STATUS: OOMKilled
3
4kubectl describe pod payments-api-<hash> -n payments
5# Containers:
6#   payments-api:
7#     State: Terminated
8#       Reason: OOMKilled
9#       Exit Code: 137
Exit code 137 means the process was killed by signal 9 (SIGKILL) — which includes OOM kills, but also any other external kill (e.g., node-level process termination). Confirm OOM specifically by checking the container state: kubectl describe pod shows OOMKilled: true in the container's last state. Kubernetes restarts the container according to restartPolicy, but the pod accumulates CrashLoopBackOff if OOM kills are frequent.
Memory limits should be set to the maximum the application should use — not the steady-state. For JVM applications, factor in heap + metaspace + off-heap; for Go applications, memory grows with concurrency. A common pattern: set memory requests to the steady-state 95th percentile usage and memory limits to 150-200% of requests, with alerts when usage exceeds 80% of the limit.
Quality of Service Classes
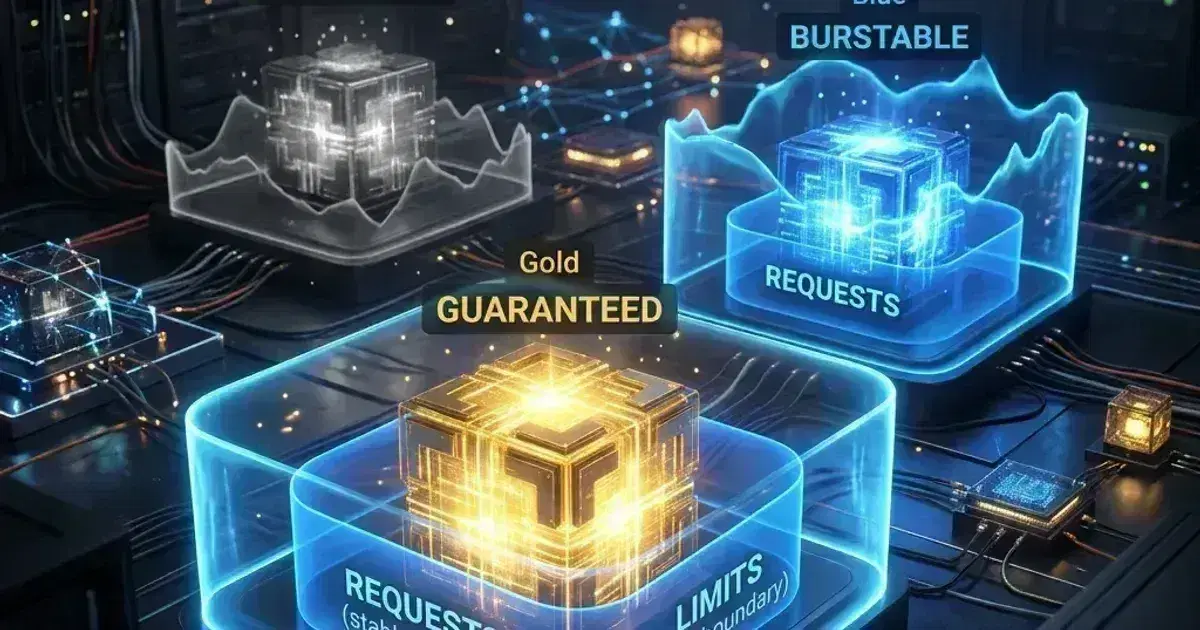
Every pod gets a QoS class based on its resource configuration. QoS controls the eviction order when a node runs low on memory:
| QoS Class | Condition | Evicted When? |
|---|---|---|
| Guaranteed | All containers have cpu.requests == cpu.limits AND memory.requests == memory.limits | Last resort — only when no other pods are evictable |
| Burstable | At least one container has requests or limits set, but requests ≠ limits for at least one resource | After BestEffort; within Burstable, pods furthest above their requests are evicted first |
| BestEffort | No resource requests or limits set on any container | First |
Within the Burstable class, the kubelet evicts pods with the highest ratio of memory usage to request first. A Burstable pod using memory at or below its request behaves similarly to Guaranteed during eviction — but it is still Burstable by class and can be evicted before Guaranteed pods.
1# Guaranteed QoS — requests equal limits for all resources
2resources:
3  requests:
4    cpu: "500m"
5    memory: "512Mi"
6  limits:
7    cpu: "500m"     # Equal to request
8    memory: "512Mi" # Equal to request
9
10# Burstable QoS — requests set, limits higher or absent
11resources:
12  requests:
13    cpu: "250m"
14    memory: "256Mi"
15  limits:
16    cpu: "1"        # Higher than request
17    memory: "512Mi" # Higher than request
18
19# BestEffort QoS — no resources set at all
20# (no resources: {} block — not recommended for production)
Use Guaranteed QoS for: CoreDNS, kube-proxy, and platform components that must survive memory pressure. The cost is CPU throttling during bursts — only use it when the workload has stable, predictable resource usage.
Use Burstable QoS for: Most production applications. They can burst during traffic spikes and are evicted after BestEffort pods.
BestEffort: Only for truly interruptible batch workloads. Don't run production services as BestEffort.
LimitRange: Namespace Defaults
LimitRange sets default requests and limits for pods in a namespace that don't specify their own. Without a LimitRange, a pod with no resource spec gets BestEffort QoS:
1apiVersion: v1
2kind: LimitRange
3metadata:
4  name: payments-defaults
5  namespace: payments
6spec:
7  limits:
8    # Container defaults: applied when a container doesn't specify resources
9    - type: Container
10      default:
11        cpu: "500m"
12        memory: "256Mi"
13      defaultRequest:
14        cpu: "100m"
15        memory: "128Mi"
16      # Hard caps: containers cannot request/limit beyond these
17      max:
18        cpu: "2"
19        memory: "2Gi"
20      min:
21        cpu: "50m"
22        memory: "64Mi"
23
24    # Pod totals (all containers combined)
25    - type: Pod
26      max:
27        cpu: "4"
28        memory: "4Gi"
When a container omits resources:, the LimitRange injects defaultRequest as the request and default as the limit, giving it Burstable QoS. Without the LimitRange, that container would be BestEffort and evicted first during node pressure.
Kubernetes Production Readiness Checklist
The pre-launch checks we run before calling a cluster production-ready — probes, resources, RBAC, upgrades, and backups. Plain Markdown you can commit to your repo.
Free. Instant download. You'll also get the occasional deep-dive from the newsletter — unsubscribe anytime.
ResourceQuota: Namespace Capacity Limits
ResourceQuota caps the total CPU, memory, and object count a namespace can consume. Use it for multi-tenant clusters where teams share a cluster:
1apiVersion: v1
2kind: ResourceQuota
3metadata:
4  name: payments-quota
5  namespace: payments
6spec:
7  hard:
8    # Compute quotas
9    requests.cpu: "8"          # Total CPU requests across all pods in namespace
10    requests.memory: 16Gi
11    limits.cpu: "16"           # Total CPU limits
12    limits.memory: 32Gi
13
14    # Object count quotas
15    pods: "50"
16    services: "10"
17    persistentvolumeclaims: "10"
18    secrets: "50"
19    configmaps: "50"
20
21    # Limit load balancers (expensive on AWS)
22    services.loadbalancers: "2"
23    services.nodeports: "0"    # Block NodePort services entirely
When a namespace has a ResourceQuota with compute quotas, every pod in that namespace must specify resource requests and limits — pods without resources will be rejected. Combine ResourceQuota with LimitRange: LimitRange provides defaults so developers don't need to specify resources on every container.
Quota Scopes
Scope quotas to specific QoS classes or priority classes:
1spec:
2  hard:
3    pods: "10"
4  scopeSelector:
5    matchExpressions:
6      - scopeName: PriorityClass
7        operator: In
8        values: ["batch-low"]    # Only count batch pods against this quota
This allows you to express "the payments team can run up to 10 batch jobs, regardless of their production quota."
Viewing Resource Usage vs Requests/Limits
1# Node-level resource usage vs capacity
2kubectl top nodes
3
4# Pod-level resource usage
5kubectl top pods -n payments
6
7# Namespace-level quota consumption
8kubectl describe resourcequota payments-quota -n payments
9# NAME             AGE   REQUEST                           LIMIT
10# payments-quota   5d    requests.cpu: 2/8, memory: 4/16  limits.cpu: 3/16, ...
11
12# View actual resource requests/limits per pod
13kubectl get pods -n payments -o custom-columns=\
14NAME:.metadata.name,\
15CPU_REQ:.spec.containers[0].resources.requests.cpu,\
16MEM_REQ:.spec.containers[0].resources.requests.memory,\
17CPU_LIM:.spec.containers[0].resources.limits.cpu,\
18MEM_LIM:.spec.containers[0].resources.limits.memory
Setting the Right Values
A repeatable process for arriving at numbers, rather than guessing:
- Measure actual usage under realistic load.
kubectl top podsfor a live snapshot; with Prometheus, pull P99 over a representative window (quantile_over_time(0.99, container_memory_working_set_bytes{...}[7d:5m])and the CPU equivalent overcontainer_cpu_usage_seconds_total). - Set requests at the P50–P75 of normal usage, not peak — requests drive scheduling, so over-sizing them wastes allocatable capacity and makes bin-packing harder without improving reliability.
- Set memory limits at P99 usage plus a 20–30% buffer — enough headroom to absorb ordinary spikes without an OOM kill, tight enough that a genuine leak still gets caught.
- Set CPU requests to match measured usage; decide on CPU limits deliberately. If you do set a CPU limit, put it at or above P99 usage — anything below that throttles the container during normal load, not just genuine runaway bursts.
VPA for Right-Sizing
Vertical Pod Autoscaler (VPA) automatically adjusts resource requests based on observed usage. Use UpdateMode: "Off" to get recommendations without automatic restarts:
1apiVersion: autoscaling.k8s.io/v1
2kind: VerticalPodAutoscaler
3metadata:
4  name: payments-api-vpa
5  namespace: payments
6spec:
7  targetRef:
8    apiVersion: apps/v1
9    kind: Deployment
10    name: payments-api
11  updatePolicy:
12 updateMode: "Off" # Recommend only — don't restart pods automatically1kubectl get vpa payments-api-vpa -n payments -o yaml | grep -A 20 recommendation
2# containerRecommendations:
3# - containerName: payments-api
4# lowerBound:
5# cpu: 50m
6# memory: 128Mi
7# target: # Use these as your requests
8# cpu: 250m
9# memory: 384Mi
10# upperBound:
11# cpu: 1
12# memory: 768MiVPA's target recommendation is the right value for requests. Run VPA in Off mode for a week, gather recommendations, then update your resource specs — before enabling Auto mode, which restarts pods to apply changes in-place.
See Kubernetes HPA and VPA: Horizontal and Vertical Pod Autoscaling for VPA installation and the interaction between VPA and HPA.
Frequently Asked Questions
Should I set CPU limits in production?
This is genuinely contested. Setting CPU limits provides isolation (workloads can't starve neighbors) but causes CPU throttling during bursts, which adds latency. Omitting CPU limits allows pods to use spare node capacity but can cause noisy-neighbor problems. The pragmatic answer: set CPU limits for latency-sensitive services but make the limit 3-5x the request to avoid throttling. Monitor container_cpu_cfs_throttled_periods_total and increase the limit if throttling exceeds 10%.
What's the difference between OOM kill and CrashLoopBackOff?
OOM kill is a specific cause: the container exceeded its memory limit and was killed. CrashLoopBackOff is a pod status meaning the container keeps crashing — repeated OOM kills are one cause, alongside startup failures, liveness probe misconfiguration, and application panics. Check kubectl describe pod and the exit code: 137 means OOM kill, 1 means application error, 143 means SIGTERM.
How do I handle init containers with different resource requirements?
Set resources on each init container independently. The scheduler computes the effective pod resource as the maximum of: (1) the largest single init container's request, OR (2) the sum of all regular container requests — whichever is greater. The two are compared, not added:
1initContainers:
2  - name: migrate
3    resources:
4      requests:
5        cpu: "500m"    # High CPU for migration — only runs at startup
6        memory: "1Gi"
7      limits:
8        cpu: "2"
9        memory: "2Gi"
10containers:
11  - name: payments-api
12    resources:
13      requests:
14        cpu: "250m"
15        memory: "256Mi"
Why does kubectl top show lower memory than my limit, but the container still OOMKills?
kubectl top reports container_memory_working_set_bytes, which excludes file-backed pages the kernel can reclaim under pressure. The OOM killer triggers on container_memory_usage_bytes, which includes those pages. A container can look comfortably under its limit in kubectl top while still being OOMKilled — check container_memory_rss in Prometheus for a closer read on actual heap usage, and don't rely on kubectl top alone to explain an OOM kill.
Is there a rule of thumb for setting initial values with no prior data?
For a typical Go or Node.js service: start with 100m CPU request, 128Mi memory request, 512Mi memory limit. For JVM services, start higher — 250m CPU request, 512Mi memory request, 1Gi memory limit — since JVM overhead (metaspace, off-heap buffers) eats into the limit before the heap does. Treat both as starting points: observe for a week under real traffic, then right-size to measured P95 using the methodology above.
For VPA that automates right-sizing of resource requests, see Kubernetes HPA and VPA: Horizontal and Vertical Pod Autoscaling. For Pod Security Standards that enforce resources: on containers (Restricted profile requires explicit resource requests), see Kubernetes Pod Security Standards and Admission Control.
Diagnosing CPU throttling or OOM kills on a production EKS cluster? Talk to us at Coding Protocols — we help platform teams set resource policies that prevent both OOM failures and the latency spikes caused by over-aggressive CPU limits.
Official References
- Managing resources for containers — requests, limits and how they map to cgroup settings
- Pod Quality of Service classes — how Guaranteed, Burstable and BestEffort affect eviction order
Was this article helpful?
Be the first to rate this article
Related Topics
Found this useful? Share it.